
// AI CLOUD
Private AI Cloud
Engineered as One System
QumulusAI combines dedicated compute, including supported bare-metal deployments, with cluster fabric, storage, orchestration, access control, security, and infrastructure support in environments designed around your workload.
Every Layer Engineered for AI Performance
Start with compute, storage, and networking, then add platform services according to the workload, data path, isolation, and operating requirements.
// GPU+CPU INFRASTRUCTURECompute
Dedicated GPU and CPU capacity for customer-controlled workloads.
// AI DATA PATHStorage
Object, file, block, local NVMe, and dedicated clusters designed around the AI data path.
// FABRIC + CONNECTIVITYNetworking
Cluster fabric, service traffic, management access, and private connectivity.
// PLATFORM SERVICESTake Dedicated AI into Production
Managed Kubernetes, Lifecycle Management, Secure AI, and AI Factory add orchestration, lifecycle automation, security controls, and production platform capabilities around your compute, storage, and networking foundation.
Managed
Kubernetes
A supported orchestration foundation for dedicated AI infrastructure.
Lifecycle Management
Automated provisioning, validation, telemetry, and lifecycle control for bare-metal infrastructure.
Secure
AI
Design layered controls across firewalls, isolation, access, data protection, operations, and deployment-specific confidential-computing requirements.
AI
Factory
A complete production AI platform spanning software, data, infrastructure, and operations.
NVIDIA GPUs for Production AI Systems
Choose the NVIDIA platform around what matters most: model development, inference economics, or enterprise operating requirements.
Rack Scale Systems
Rack-scale systems deliver the highest performance for large-scale training, reasoning, and inference. VR200 NVL72 and GB300 NVL72 connect 72 GPUs in one NVLink domain with Arm-architecture NVIDIA Vera or Grace CPUs. VR200 specifications are preliminary; configuration, availability, region, and timing are confirmed for each deployment.
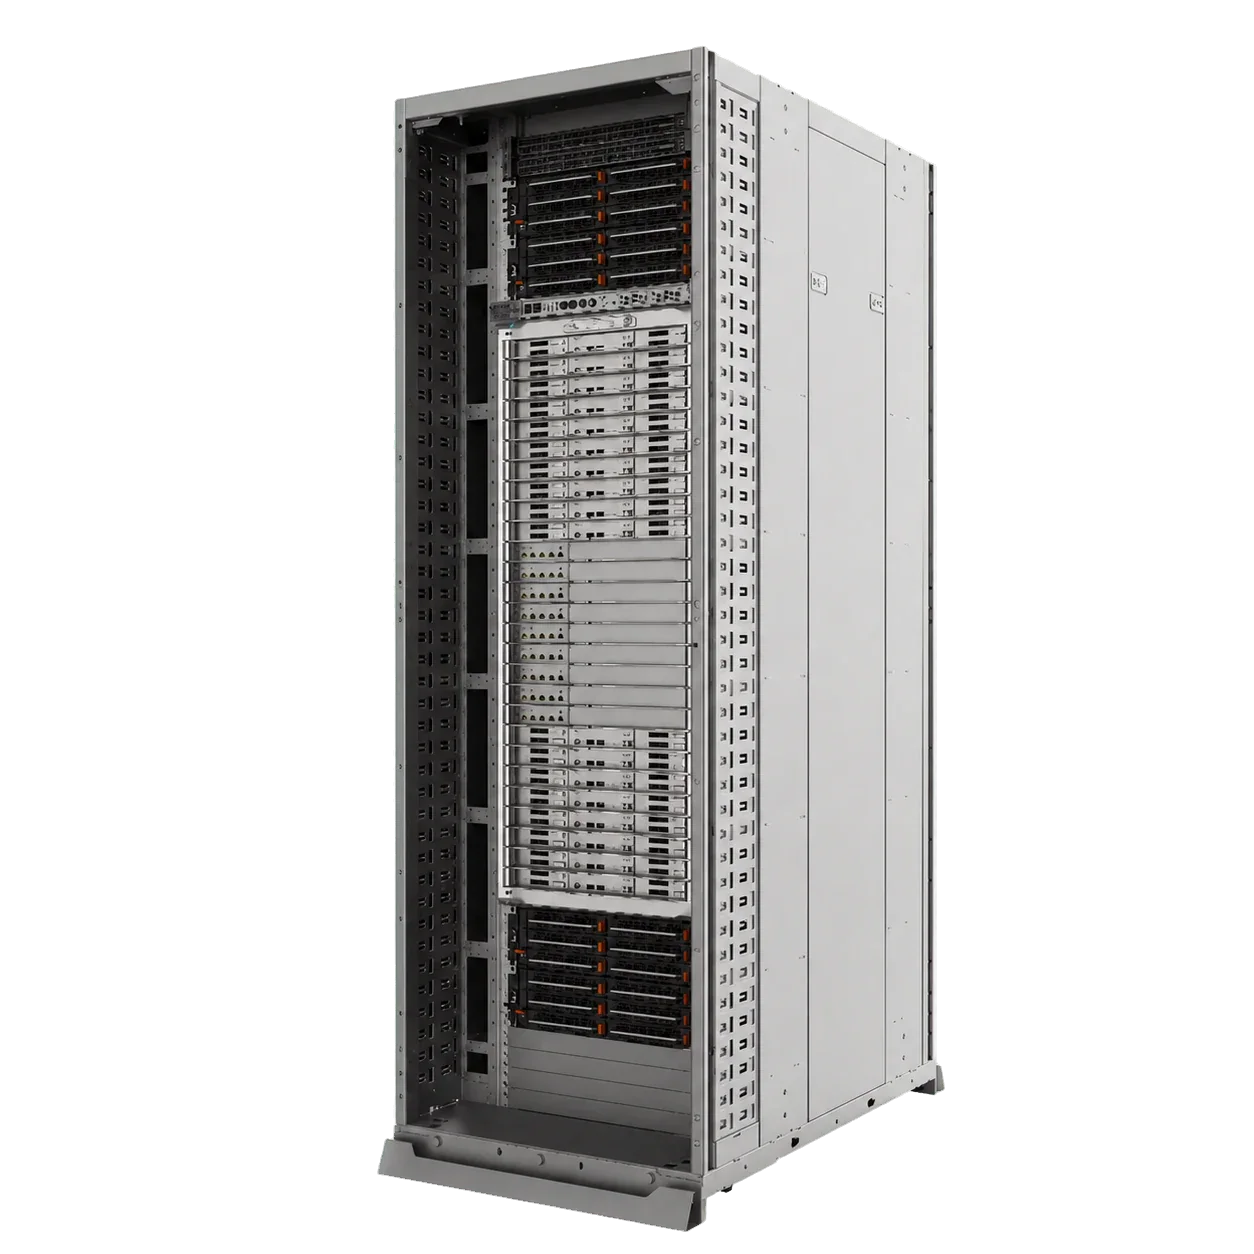
Vera Rubin NVL72
Next-generation agentic AI, long-context reasoning, and large-scale training
GPU COUNT72 per rack
VRAM PER GPU288 GB HBM4
VRAM PER RACK20.7 TB
CPU CORES3,168 cores
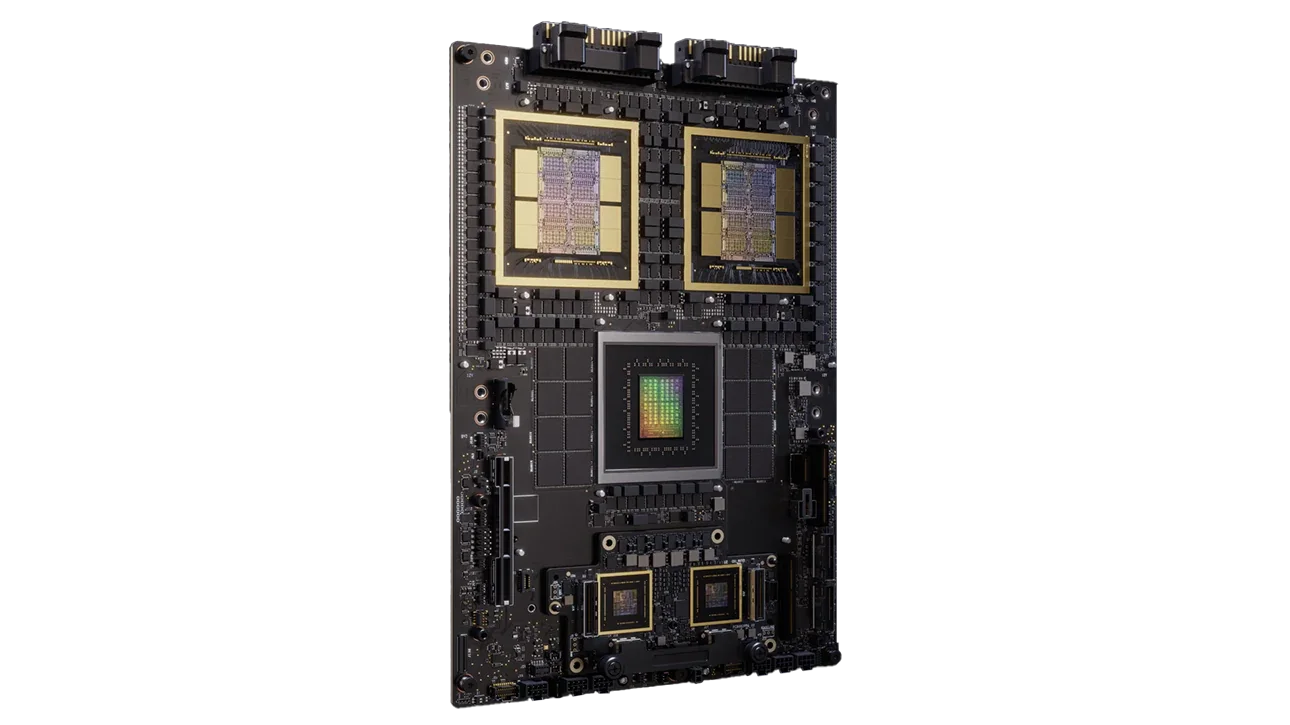
GB300
Rack-scale reasoning, training, and high-throughput inference
GPU COUNT72 per rack
VRAM PER GPU288 GB HBM3e
VRAM PER RACK20.7 TB
CPU CORES2,592 cores
Blackwell Systems
Blackwell systems are built for large-model training, reasoning, high-throughput inference, multimodal AI, and enterprise visual computing.
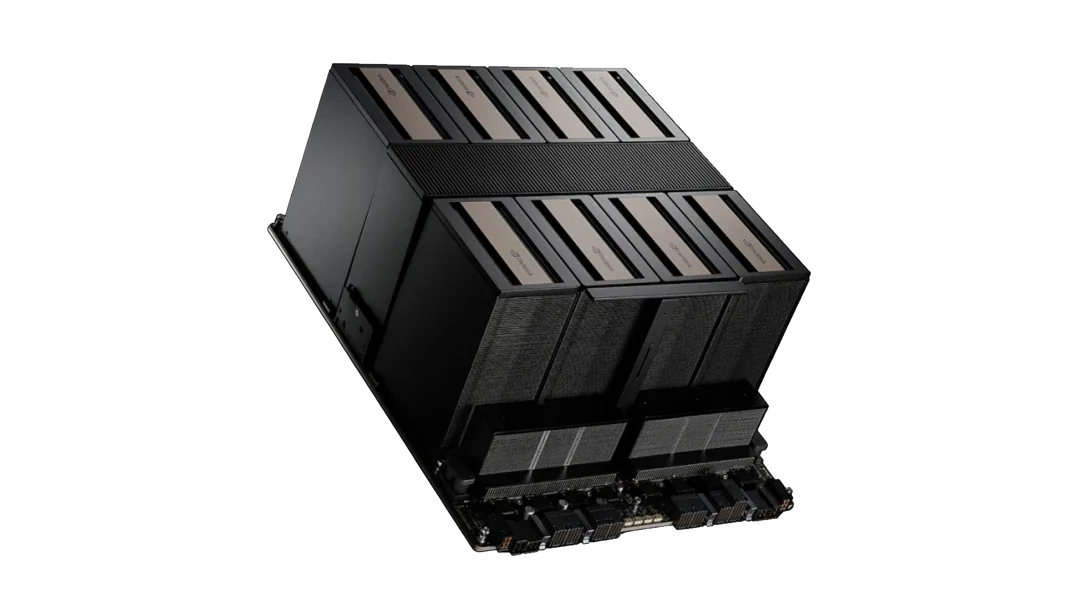
B300
Memory-intensive training, reasoning, and high-throughput inference
GPU COUNT8 per node
VRAM PER GPU288 GB HBM3e
VRAM PER RACK2,304 GB
CPU CORES256 vCPUs
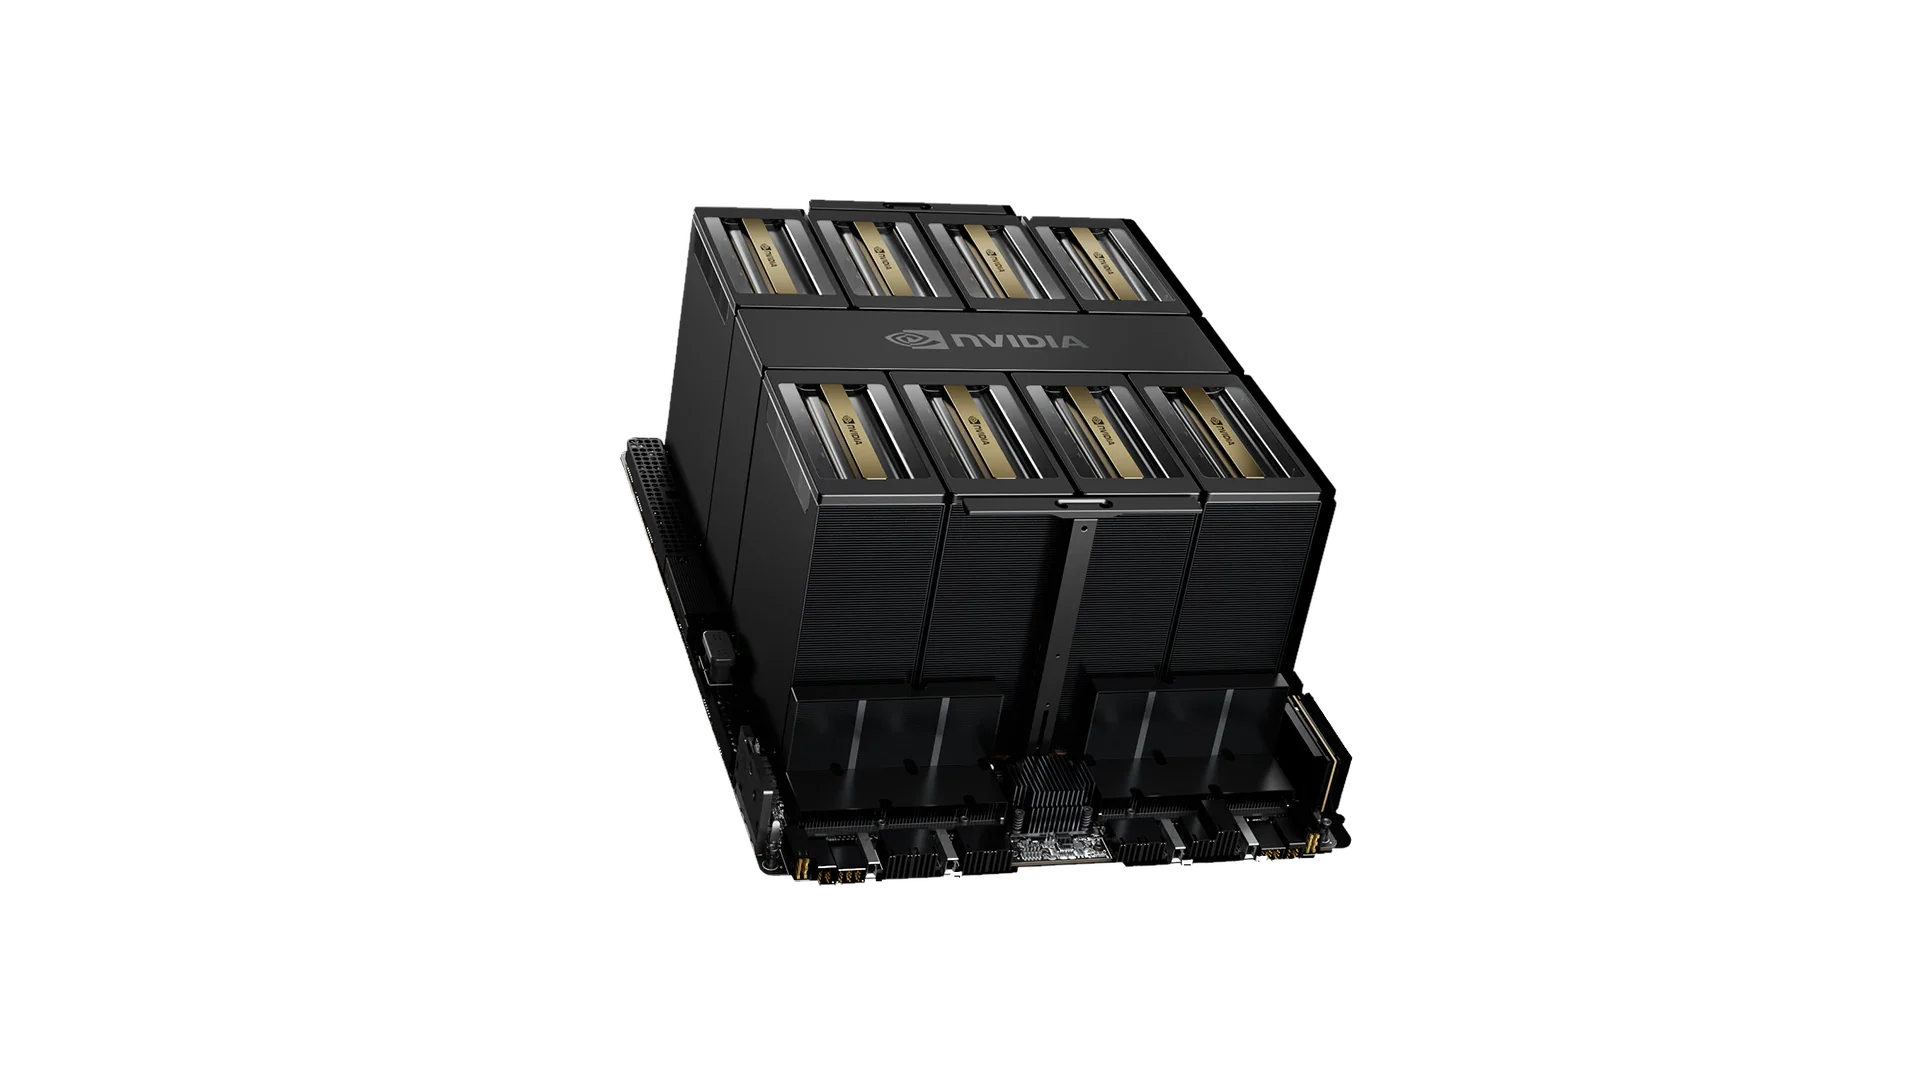
B200
Large-model training and production inference at scale
GPU COUNT8 per node
VRAM PER GPU180 GB HBM3e
VRAM PER RACK1,440 GB
CPU CORES224 vCPUs
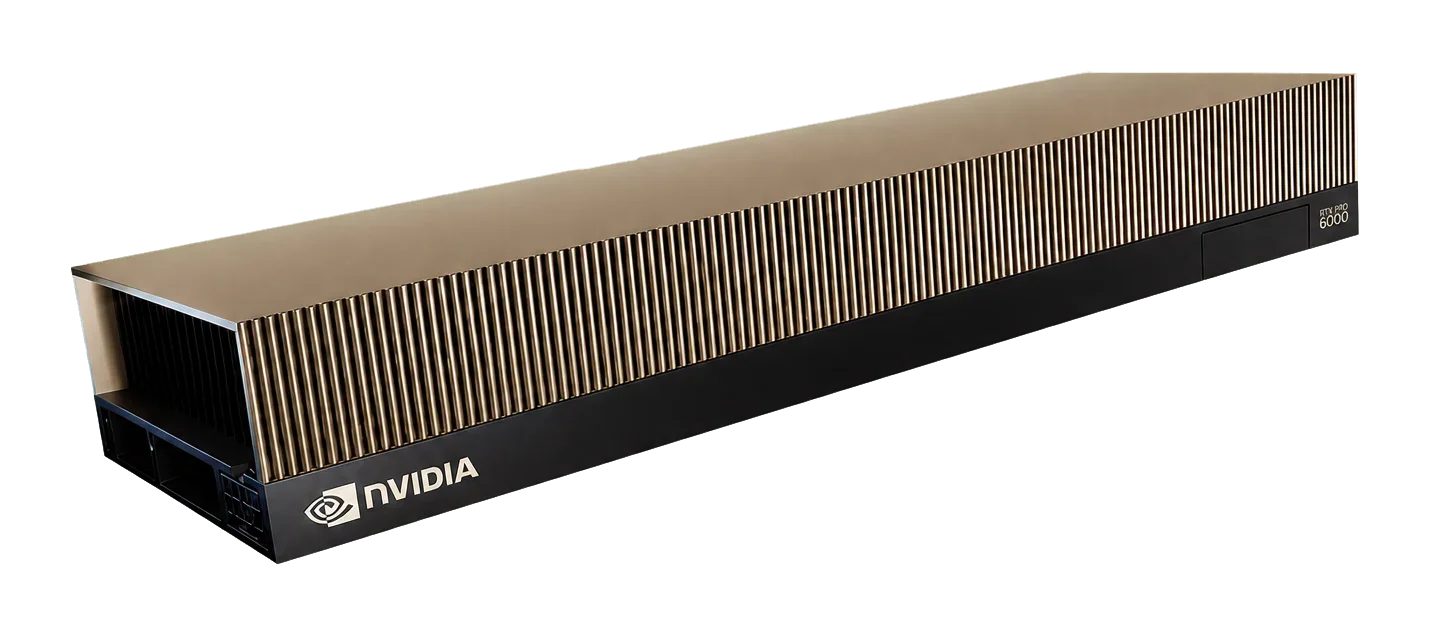
RTX Pro 6000
Enterprise AI, video, graphics, simulation, and visualization
GPU COUNT8 per node
VRAM PER GPU96 GB HBM3e
VRAM PER RACK768 GB
CPU CORES384 vCPUs
Hopper Systems
Hopper systems support large-model inference, training, fine-tuning, and HPC, with H200 providing more memory for larger models and longer contexts.
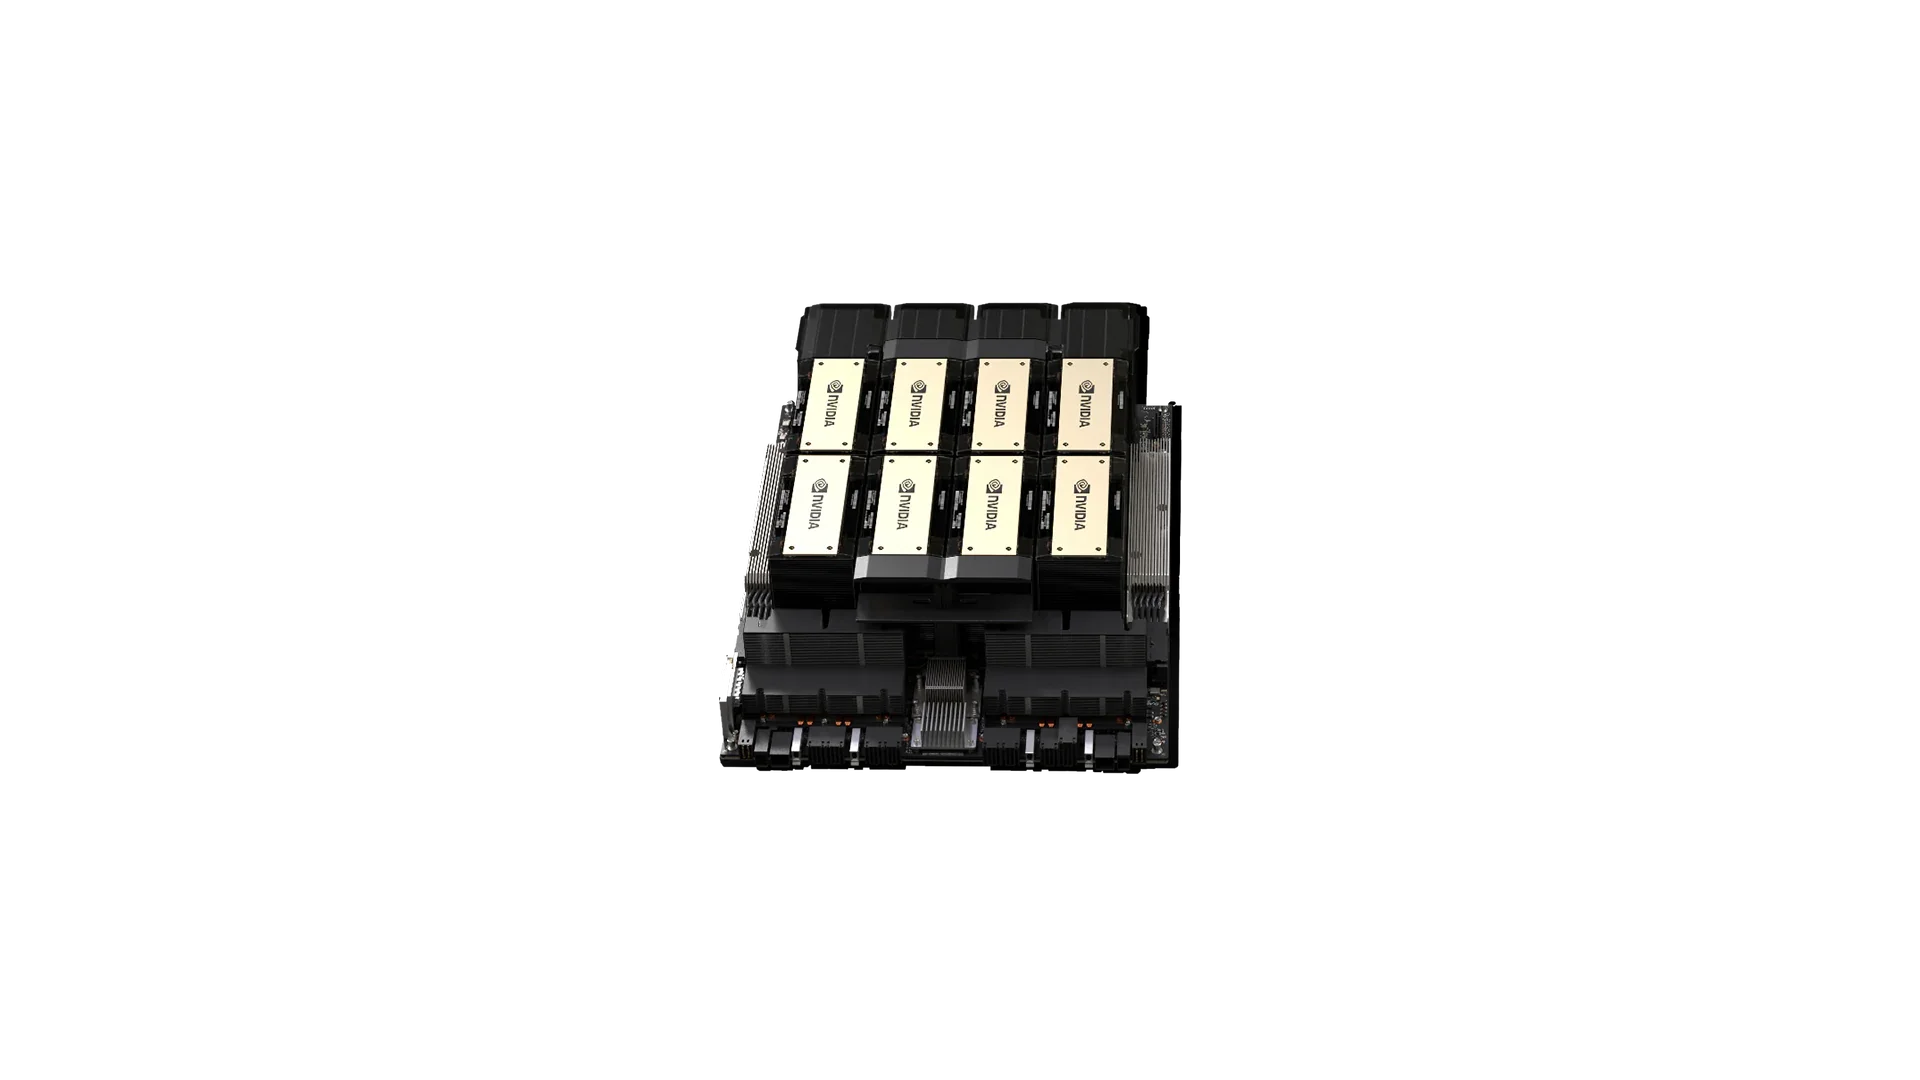
H200
Larger models, longer contexts, and memory-intensive HPC
GPU COUNT8 per node
VRAM PER GPU141 GB HBM3e
VRAM PER RACK1,128 GB
CPU CORES128 vCPUs
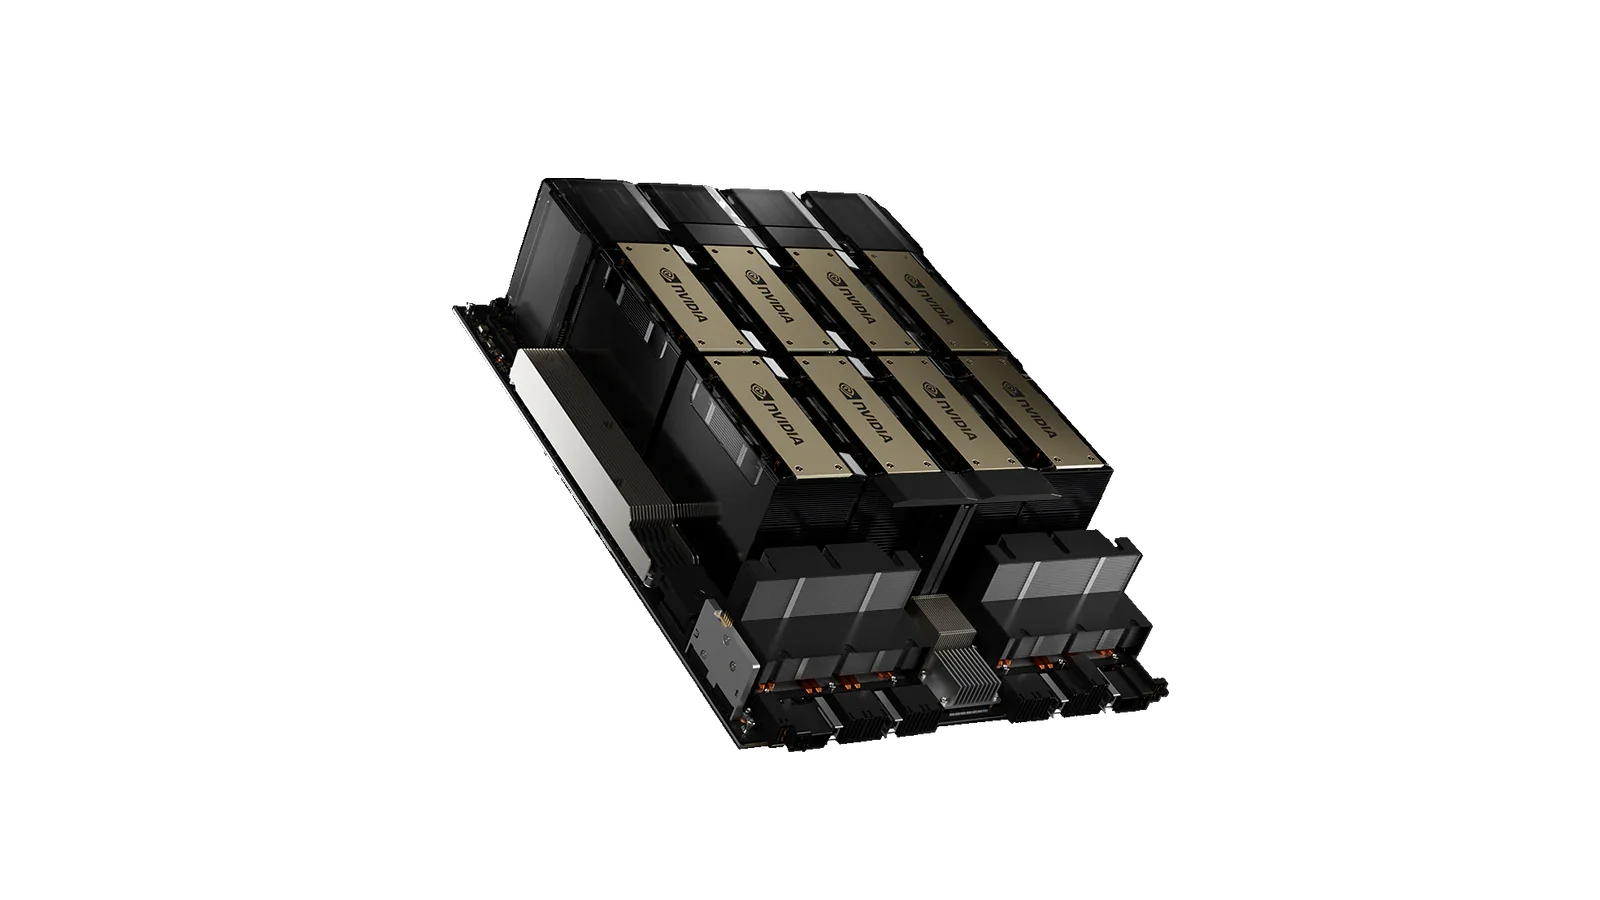
H100
Established Hopper infrastructure for training, inference, and HPC
GPU COUNT8 per node
VRAM PER GPU80 GB HBM3
VRAM PER RACK640 GB
CPU CORES224 vCPUs
Reserve Cluster Capacity with Room to Grow
Reserved clusters provide a predictable pool of dedicated infrastructure for steady workloads. Expansion planning can be incorporated into the design so future nodes, storage, or network capacity do not require a new architecture.
B300 Clusters
Memory-intensive model training, reasoning, and high-throughput inference.
CLUSTER SIZE64 – 1,024 nodes | 512 – 8,192 GPUS
FABRIC6.4 Tbps aggregate RoCEv2
ORCHESTRATIONKubernetes & Slurm
GPUS PER NODE8× B300 288 GB HBM3e SXM6
GPU MEMORY PER NODE2,304 GB
LOCAL NVME PER NODE15.36 TB
B200 Clusters
Large-model training, fine-tuning, and production inference.
CLUSTER SIZE64 – 1,024 nodes | 512 – 8,192 GPUS
FABRIC3.2 Tbps aggregate RoCEv2
ORCHESTRATIONKubernetes & Slurm
GPUS PER NODE8× B200 180 GB HBM3e SXM6
GPU MEMORY PER NODE1,440 GB
LOCAL NVME PER NODE15.36 TB
H200 Clusters
Memory-heavy Hopper training, inference, and HPC workloads.
CLUSTER SIZE64 – 1,024 nodes | 512 – 8,192 GPUS
FABRIC3.2 Tbps aggregate RoCEv2
ORCHESTRATIONKubernetes & Slurm
GPUS PER NODE8× H200 141 GB HBM3e SXM5
GPU MEMORY PER NODE1,128 GB
LOCAL NVME PER NODE15.36 TB
Vera Rubin NVL72 Clusters
Rack-scale reasoning, training, and high-throughput inference
CLUSTER SIZE2-80 racks
GPU COUNT72 per rack
VRAM PER GPU288 GB HBM4
VRAM PER RACK20.7 TB
CPU CORES3,168 cores
GB300 NVL72 Clusters
Rack-scale reasoning, training, and high-throughput inference
CLUSTER SIZE4-112 racks
GPU COUNT72 per rack
VRAM PER GPU288 GB HBM3e
VRAM PER RACK20.7 TB
CPU CORES2,592 cores